RT-2-X
Multi-robot vision-language-action model from the Open X-Embodiment project.
About
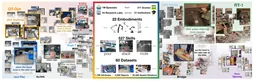
RT-2-X is Google DeepMind's vision-language-action model trained on the Open X-Embodiment dataset, released October 2023 alongside the dataset and the smaller RT-1-X. The project pooled data from 22 robot embodiments across 20 institutions: over 1 million episodes covering 500+ skills and 150,000 tasks, released as the largest open real-robot dataset of its kind. RT-2-X builds on RT-2's web-scale vision-language pretraining, giving it emergent semantic understanding: it can interpret abstract commands and transfer web knowledge into robot actions it was never explicitly trained for.
DeepMind reported RT-2-X achieved 3x performance improvement over models trained per-robot, demonstrating that cross-embodiment training generalizes better than narrow specialists. Both the dataset and the trained models were open-sourced, seeding years of follow-on robotics research. Exact release date is era-level (October 2023) and flagged as such.
Specs
Context window
Pricing
Free quota
API access
Weights
Released
Benchmarks
Provider-reported unless a source says otherwise. Benchmarks are marketing-adjacent by nature — treat them as directional.
Use cases
Trust score — 8/10
Scored 8/10 (verified tier, metrics-v1). Evidence: Verified via vendor site/docs/GitHub and reputable coverage, wave 92; Trending score 80/100 from researcher assessment.